Overview
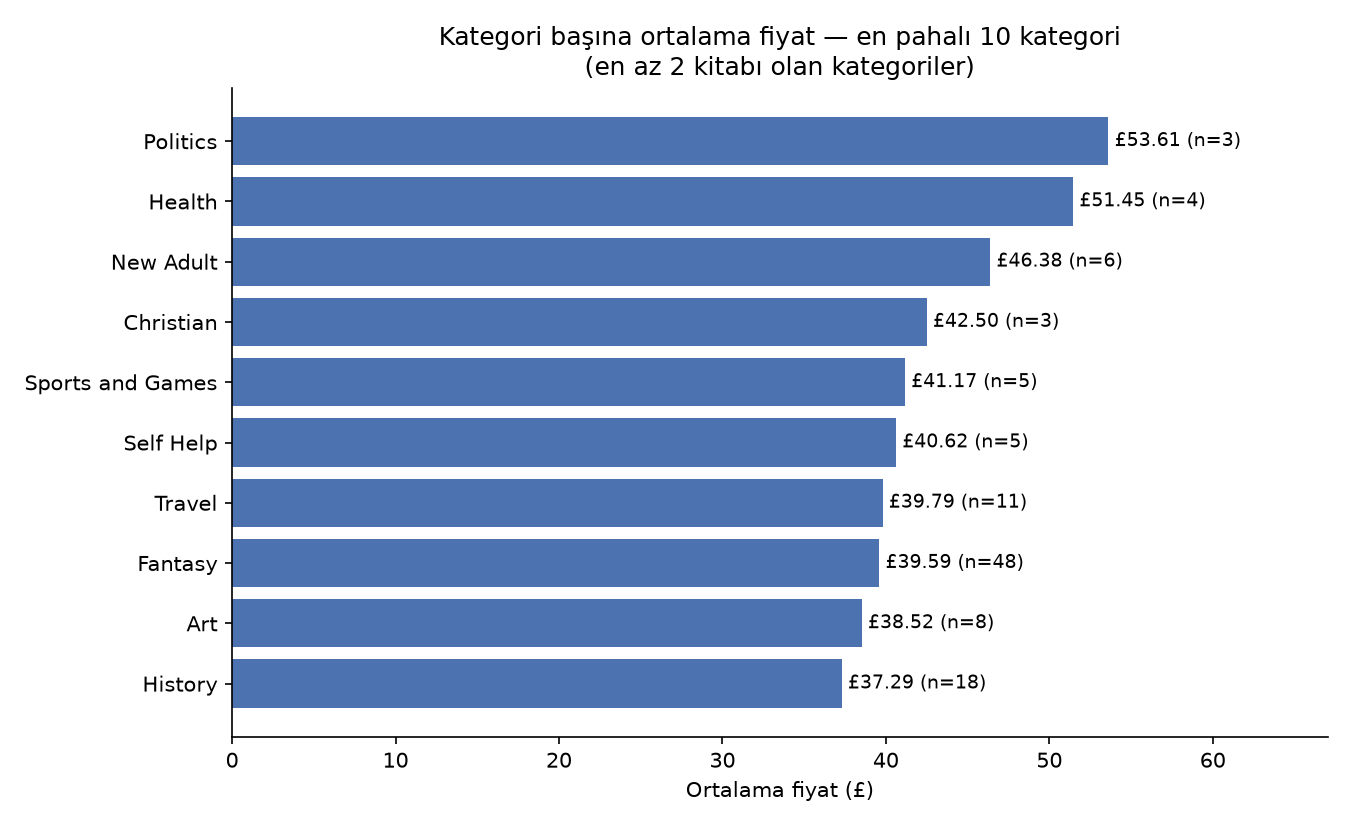
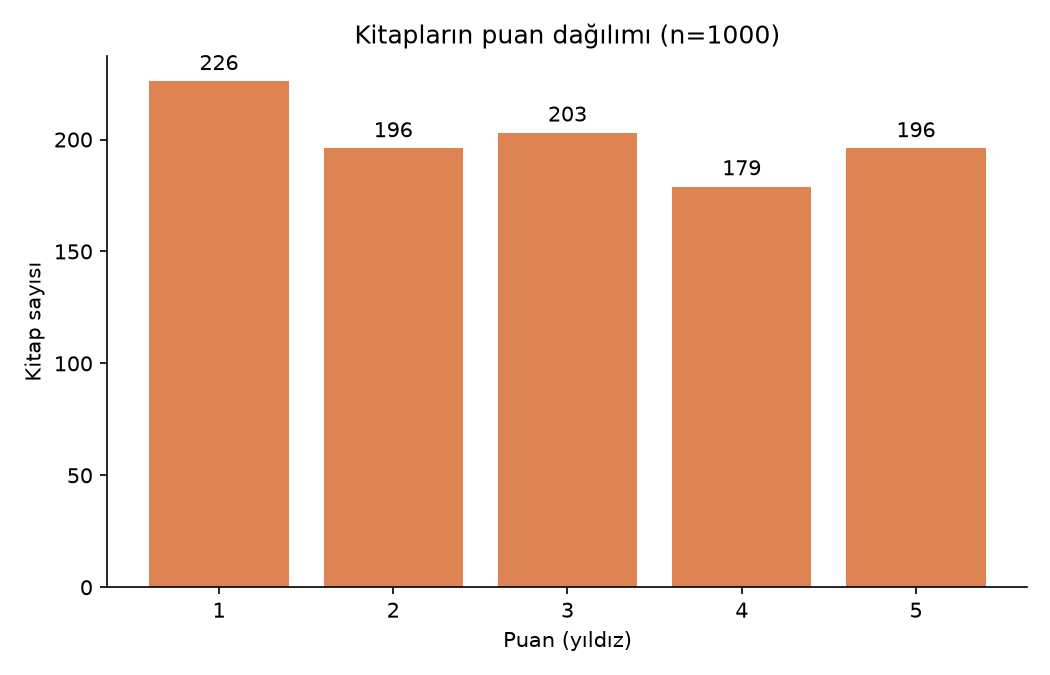
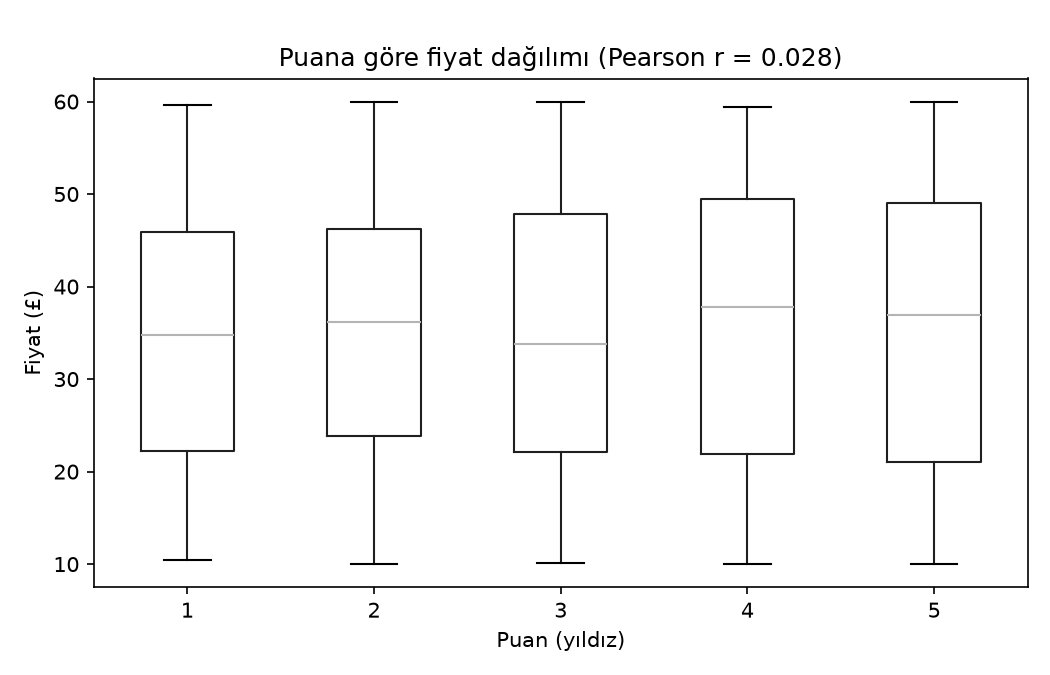
scrape.py follows the next link across 50 listing pages and visits every detail page for category and stock count, fields that only exist there. Prices and star ratings are parsed with small, unit-tested helpers. Each request waits 0.5 s, times out at 15 s and retries up to three times with backoff; a broken book page yields None fields instead of a crash. When the run ends, the row count is checked against the total printed on the site. analiz.py produces three charts and a written answer. The project was built alongside Claude Code with a rule file, a prompt log and a reflection report committed to the repo.
Highlights
- Three test layers: unit parsers with no network, integration against the live site, and an end-to-end run through a temporary directory.
- Ethical defaults: identifying User-Agent, enforced minimum delay, no parallel requests.
- Paths resolve relative to the script, so it runs from any working directory and creates its own output folders.
Figures